- You want one or more tasks to automatically run again if they fail.
- You need to manually rerun a failed task for one or multiple Dag runs.
- You want to deploy a Dag with a start date of one year ago and trigger all Dag runs that would have been scheduled in the past year.
- You have a running Dag and realize you need it to process data for two months prior to the Dag’s start date.
Assumed knowledge
To get the most out of this guide, you should have an understanding of:- Dag scheduling. See Schedule Dags in Airflow
Automatically retry tasks
In Airflow, you can configure tasks to retry automatically when they fail. You can set a fixed number of retries with a delay between them using retry parameters, and in Airflow 3.3+ you can use retry policies to decide how to handle a failure based on the exception that caused it.Retry parameters
The following task parameters control the retry behavior of a task. Some of them have an Airflow configuration that sets the default for all tasks in your Airflow environment.
It’s common practice to set the retry parameters for all tasks in a Dag with
default_args and override them for specific tasks as needed.
The following Dag contains four tasks that always fail. Each of the tasks uses a different retry parameter configuration.
Retry policies
In Airflow 3.3+, you can attach a retry policy to a task with theretry_policy parameter. When a task instance fails, the retry policy evaluates the exception and decides what happens next. For example, you can retry a task instance that failed because of an error that is likely transient, such as a 503 error, and fail a task instance immediately that failed because of an error that requires manual intervention, such as invalid credentials.
The following example attaches an ExceptionRetryPolicy to a task. The policy contains one RetryRule, which maps the PermissionError exception to the RetryAction.FAIL action:
load_orders raises a PermissionError, the task instance fails immediately instead of using its three retries. Any other exception uses the retry behavior defined on the task.
Internally, every retry policy returns a RetryDecision object that contains the action, and optionally a delay and a reason. You only use RetryDecision in your code when you write a custom retry policy.
Each decision is written to the task logs, for example:
AirflowFailException and AirflowSensorTimeout always fail the task instance immediately. Airflow doesn’t evaluate the retry policy for these exceptions.- Exception retry policy: Maps exception types to retry actions.
- AI-based retry policies:
LLMRetryPolicyandClassifierRetryPolicyuse a model to classify the failure. Requires the Common AI provider. - Chain retry policy: Combines several retry policies in order.
- Custom retry policy: Defines your own logic in a subclass of
RetryPolicy.
Retry actions
There are four possible retry actions:-
RetryAction.DEFAULT: Use the retry behavior defined by the retry parameters on the task itself. -
RetryAction.FAIL: Fail the task instance immediately without using its remaining retries. -
RetryAction.RETRY: Retry the task instance, optionally with a different delay. The maximum total number of retries a task instance can get is limited by theretriesparameter. -
RetryAction.RESCHEDULE: Airflow 3.4+. Run the task instance again later without using a retry. Airflow sets the state of the task instance toup_for_reschedule. When you use this action, you need to setmax_reschedules,reschedule_timeout, or both on theRetryRuleorRetryDecision.max_reschedulesdetermines how often the task instance can be rescheduled.reschedule_timeoutdetermines how much time can pass after the first reschedule before Airflow stops rescheduling the task instance. After that, Airflow uses the retry behavior defined on the task, including itsretry_delayinstead of theretry_delayof the rule. Both limits apply per try: when the task instance is retried, for example because a different rule returnsRetryAction.RETRY, the count and the time start over.
RetryAction.RETRY and RetryAction.RESCHEDULE:
Exception retry policy
ExceptionRetryPolicy maps exception types to actions with a list of RetryRule objects. Each rule defines the exception, the action, and optionally a custom retry delay and a reason. Airflow evaluates the rules in order and the first rule that matches the exception wins. If no rule matches, the task instance uses the retry behavior defined on the task.
You can define the exception of a rule as an exception class, as a dotted import path string, or as a list of either. By default, a rule also matches subclasses of the exception. Set match_subclasses=False to only match the exact exception type.
- A
TimeoutErrorretries after 30 seconds. The rule uses the exception class. - A plain
OSError, such as a generic input/output error, retries after two minutes. The rule uses a dotted import path andmatch_subclasses=False, so it doesn’t match subclasses ofOSErrorsuch asFileNotFoundErrorandPermissionError. Withoutmatch_subclasses=False, this rule would retry those errors too.TimeoutErroris also a subclass ofOSError, but the first rule already matches it. - A
FileNotFoundErrororPermissionErrorfails the task instance immediately. The rule uses a list that combines an exception class and a dotted import path. - Any other exception, such as a
ValueError, uses the retry behavior defined on the task.
AI-based retry policies
The Common AI provider includes two retry policies that use a model to classify the failure. Both send the exception message to the model provider of your connection.LLMRetryPolicy: A text model classifies the failure and decides whether to retry and how long to wait, based on yourinstructions.ClassifierRetryPolicy: A classifier model sorts the failure into one of thecategoriesyou define, and the matchingErrorCategorydecides whether the task instance retries and after how long.
By default, both policies mask values that Airflow registered as secrets, such as connection passwords, but not other sensitive information in the exception message. Use the
redactor parameter to define your own masking. See Custom redactors in the Common AI provider documentation.model_id parameter of the policy to override the model of the connection.
The following example uses an LLMRetryPolicy with a text model. If the model call fails, the policy uses its fallback_rules:
ClassifierRetryPolicy with a decision model and three categories:
Chain retry policy
In Airflow 3.4+,ChainRetryPolicy combines several retry policies. Airflow evaluates the policies in order, and the first decision that isn’t RetryAction.DEFAULT wins.
If a policy raises an error, for example because of a bug in the policy code, Airflow evaluates the next policy.
ClassifierRetryPolicy.
- If the failure is a
PermissionError,known_failuresfails the task instance immediately without calling the model. - If the failure isn’t a
PermissionError, the decision model classifies it. If the model classifies the failure aswarehouse_suspendedwith a confidence of at least 0.8, the task instance retries after 30 seconds. - If the failure matches neither, the decision model classifies it as
other. This category doesn’t define a delay, so the task instance retries with theretry_delaydefined on the task, after one minute.
Custom retry policies
You can also implement a custom retry policy by subclassingRetryPolicy and implementing its evaluate() method. This lets you inspect exception attributes or use context that ExceptionRetryPolicy doesn’t have access to.
Some errors can only be distinguished by an attribute on the exception rather than by the exception class itself. For example, Snowflake errors carry an error code in their errno attribute. A custom policy can implement retry logic on those attributes:
Automatically pause a failing Dag
You can configure Airflow to automatically pause a Dag after a certain number of failed Dag runs, preventing a failing Dag from continuing to run and potentially causing more issues. To set the maximum number of consecutive failed Dag runs for all your Dags in your Airflow environment, set thecore.max_consecutive_failed_dag_runs_per_dag config. For example, to automatically pause all your Dags after they had 5 failed Dag runs in a row, set:
max_consecutive_failed_dag_runs parameter in the Dag instantiation. For example, to pause a specific Dag after 3 failed Dag runs in a row, set:
- TaskFlow
- Traditional
Manually rerun tasks or Dags
Rerunning tasks or full Dags in Airflow is a common workflow. To rerun a task in Airflow, you clear the task instance. Clearing sets the state of the task instance toNone, so the scheduler runs it again. A cleared task instance gets its full number of retries again, no matter how many tries it used before.
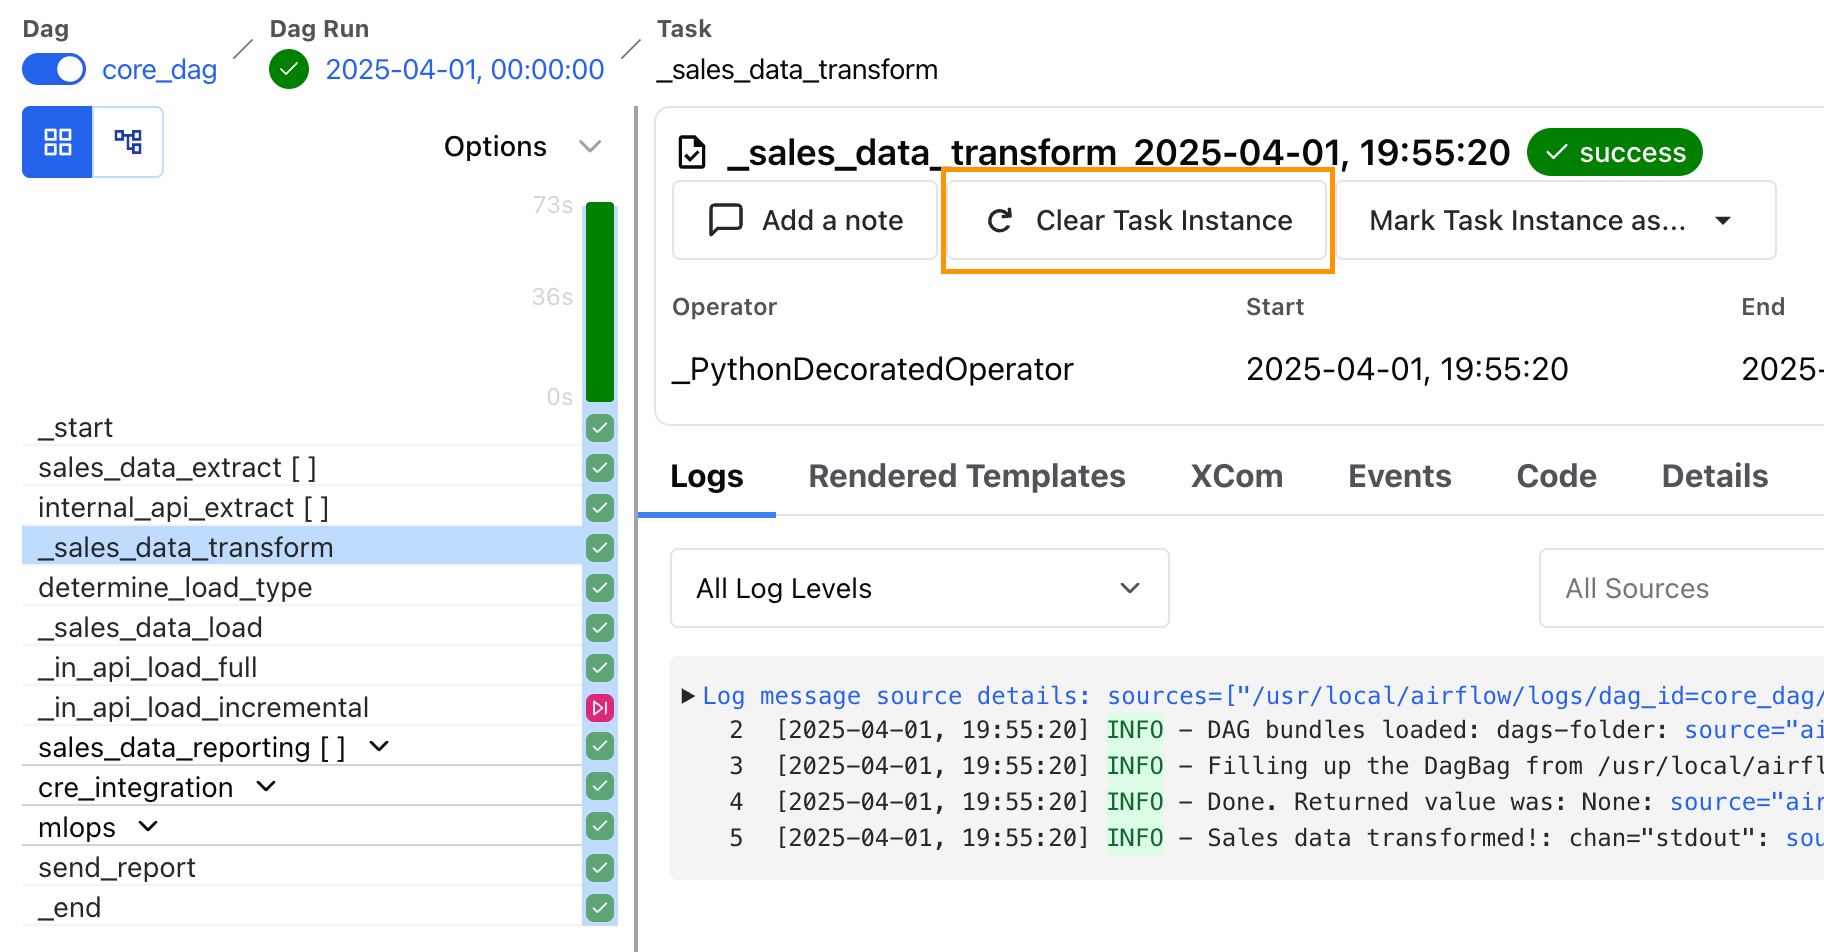
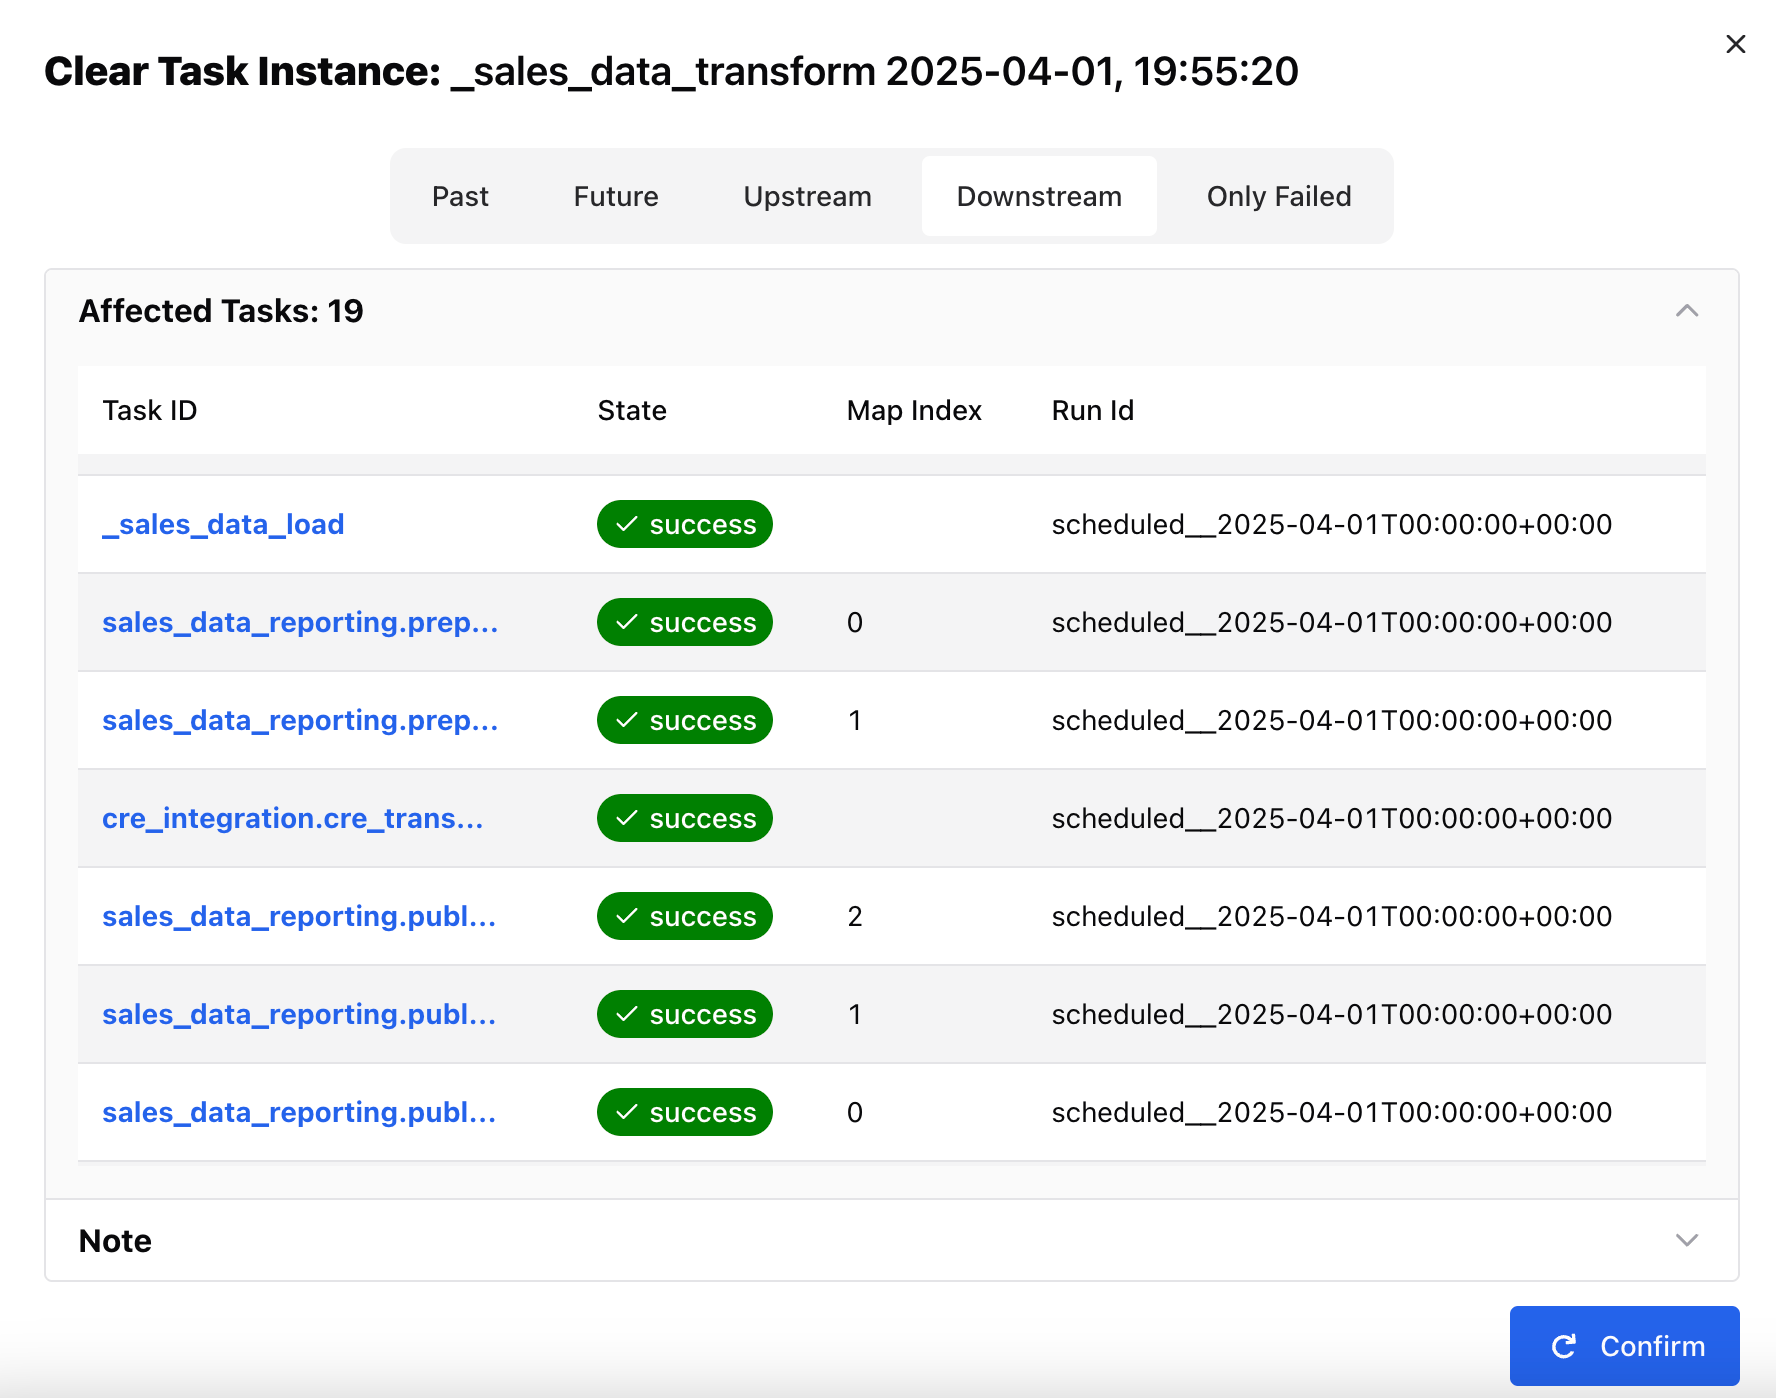
To clear a task instance, go to your Dag in the Airflow UI, select the task instance you want to rerun, and click Clear Task Instance.
- Past: Clears any instances of the task in Dag runs with a logical date before the selected task instance.
- Future: Clears any instances of the task in Dag runs with a logical date after the selected task instance.
- Upstream: Clears any tasks in the current Dag run which are upstream from the selected task instance.
- Downstream: Clears any tasks in the current Dag run which are downstream from the selected task instance.
- Clear only failed tasks: Clears only failed instances of any task instances selected based on the previous options.
- Keep task state and resume: Keeps the task state store entries of the cleared task instances. By default, clearing a task instance discards them. See Clearing behavior.
- Prevent rerun if task is running: Skips task instances that are currently running.
- Run with latest bundle version: Runs the task instances with the latest version of the Dag code. This option only appears for Dags in a versioned Dag bundle when the Dag changed since the Dag run. See Run on latest version.
POST /api/v2/dags/{dag_id}/clearTaskInstances endpoint of the Airflow REST API.
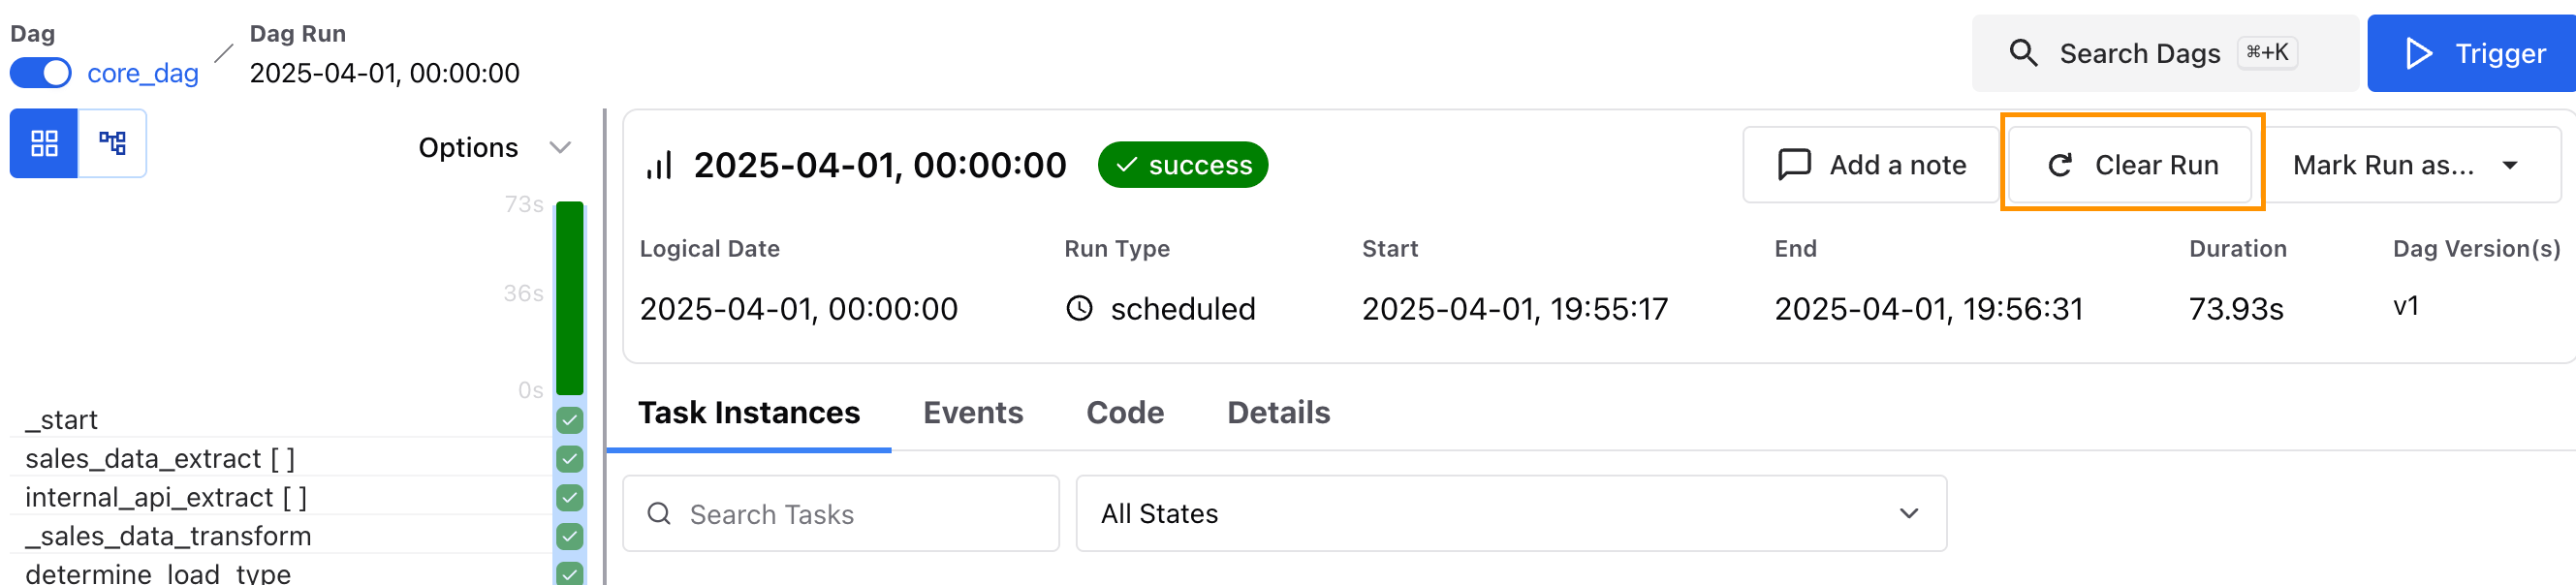
To clear a full Dag run, click the Dag run, and then click Clear Dag Run as shown in the following image.
Add notes to cleared tasks and Dags
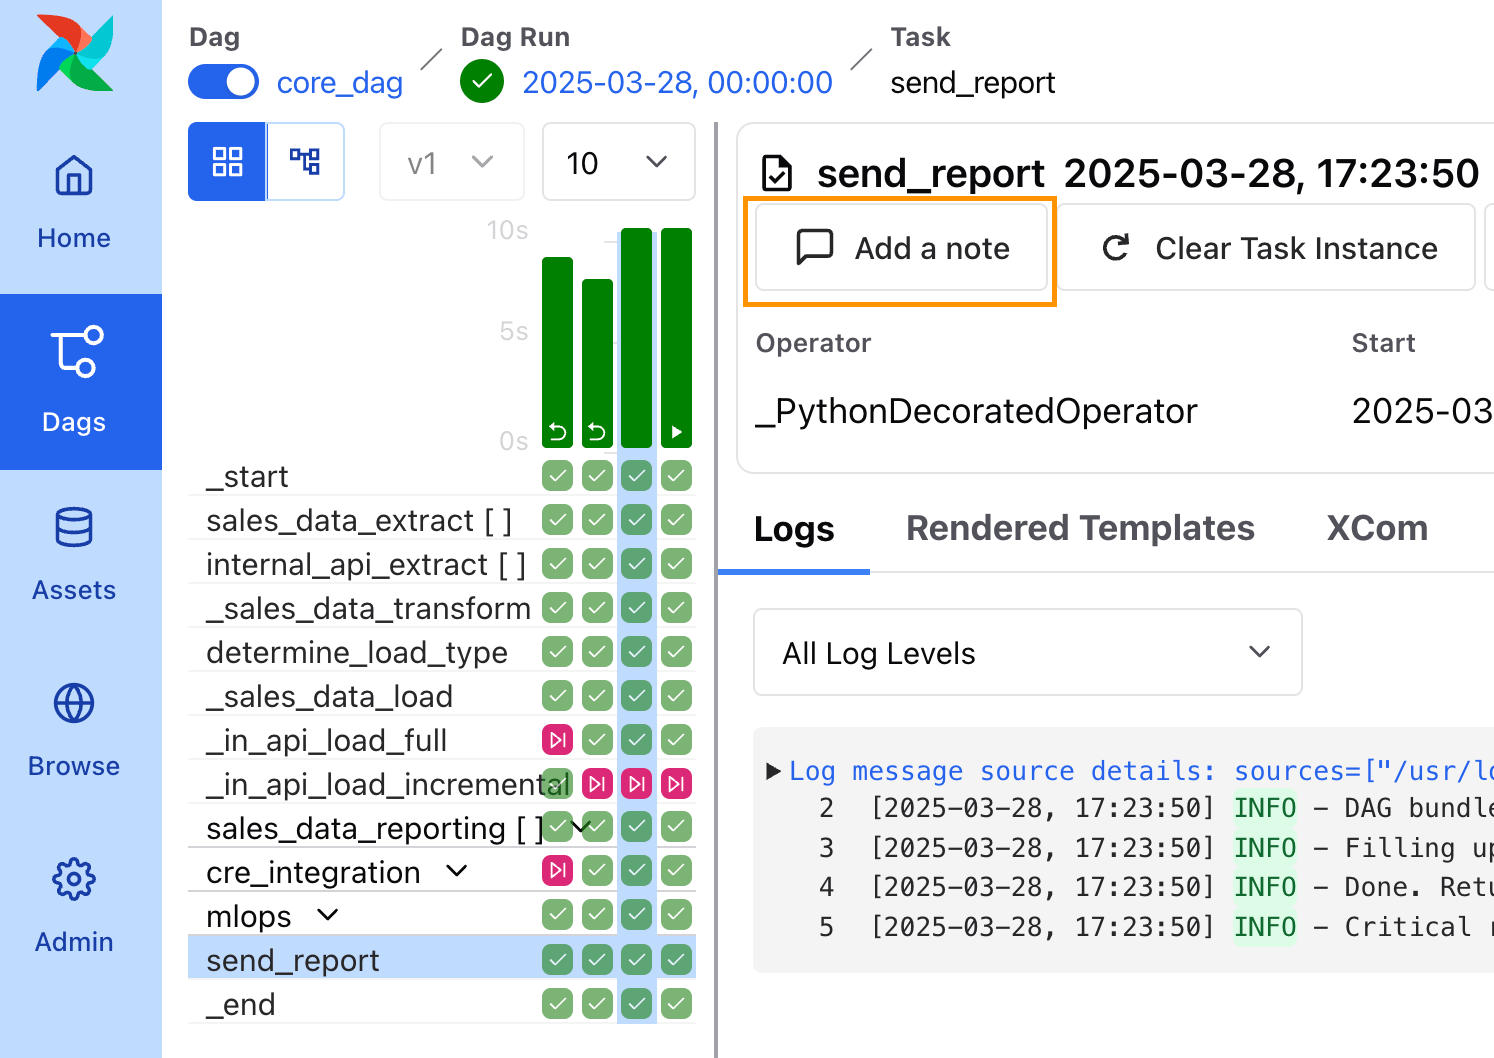
You can add notes to task instances and Dag runs in the Airflow UI. This feature is useful for tracking manual changes to task instances, such as reruns or task status changes. Astronomer recommends leaving a note on a task or Dag whenever you manually update a task instance through the Airflow UI. To add a note to a task instance or Dag run:- Go to your Dag in the Airflow UI.
- Select a task instance or Dag run.
- Click Add a note.
- Write a note and click Confirm.
Catchup
You can use the built-in catchup Dag argument to process data for logical dates between the setstart_date of a Dag and the current date.
When the catchup parameter for a Dag is set to True, at the time the Dag is turned on in Airflow, the scheduler starts a Dag run for every data interval that hasn’t been run between the Dag’s start_date and the current data interval. For example, if your Dag is scheduled to run daily and has a start_date of 1/1/2025, and you deploy that Dag and turn it on 2/1/2025, Airflow will schedule and start all of the daily Dag runs for January. Catchup is also triggered when you turn a Dag off for a period and then turn it on again.
Catchup can be controlled by setting the parameter in your Dag’s arguments. By default, catchup is set to False. This example Dag has catchup turned on:
True, Airflow will schedule numerous Dag runs all at once. When using catchup, keep in mind what resources Airflow has available and how many Dag runs you can support at one time. To avoid overloading your scheduler or external systems, you can use the following parameters in conjunction with catchup:
max_active_runs: Set at the Dag level and limits the number of Dag runs that Airflow will execute for that particular Dag at any given time. For example, if you set this value to 3 and the Dag had 15 catchup runs to complete, they would be executed in 5 chunks of 3 runs.depends_on_past: Set at the task level or as adefault_argfor all tasks at the Dag level. When set toTrue, the task instance must wait for the same task in the most recent Dag run to be successful. This ensures sequential data loads and allows only one Dag run to be executed at a time in most cases.wait_for_downstream: Set at the task level or as adefault_argfor all tasks at the Dag level. When set toTrue, the task instance waits for the same task in the previous Dag run and the tasks immediately downstream of it to succeed or be skipped. Settingwait_for_downstreamtoTruealso setsdepends_on_pasttoTrue.
AIRFLOW__SCHEDULER__CATCHUP_BY_DEFAULT to True.
If you want to deploy your Dag with catchup enabled but there are some tasks you don’t want to run during the catchup, you can use the LatestOnlyOperator in your Dag. This operator only runs during the Dag’s most recent scheduled interval. In every other Dag run it is ignored, along with any tasks downstream of it.
Backfill
Backfilling is the concept of running a Dag for a specified period in the past to re-process historical or missed data. Unlike catchup, which triggers missed Dag runs from the Dag’sstart_date through the current data interval, backfill periods can be specified explicitly and can include periods prior to the Dag’s start_date.
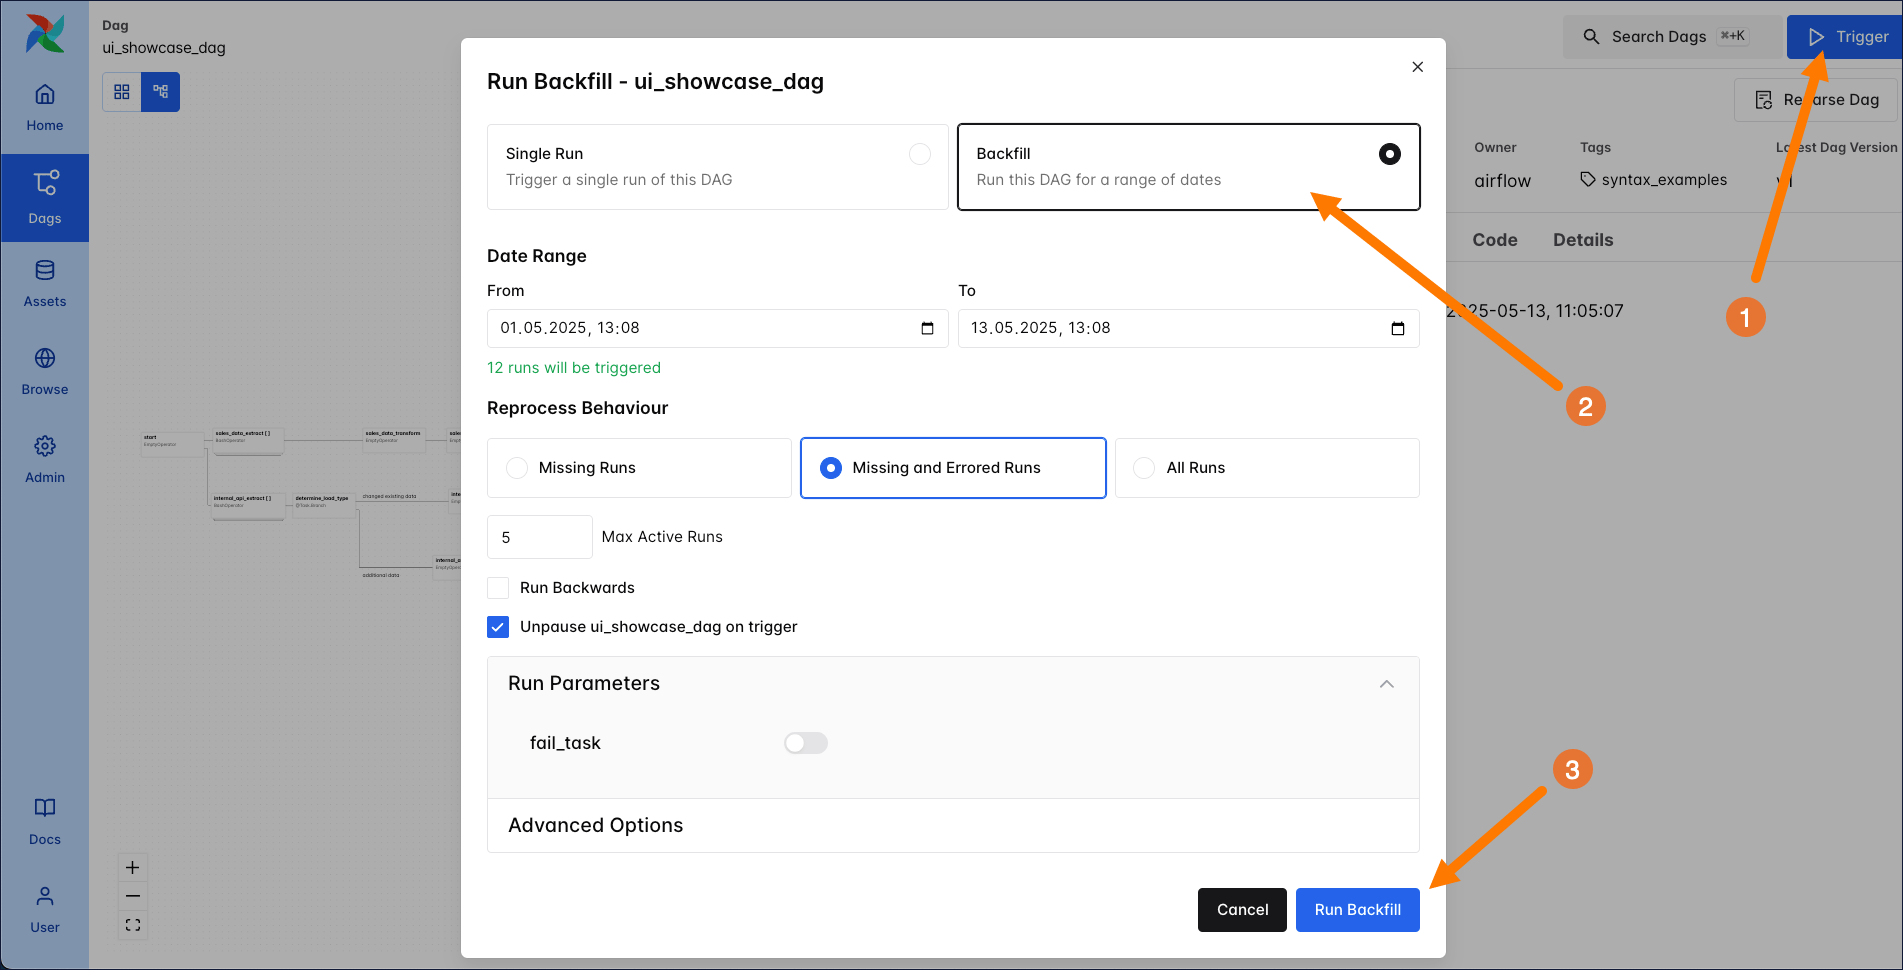
In Airflow 3, backfills are managed by the scheduler and can be triggered through the UI, API, or CLI. To run a backfill from the UI, click the blue Trigger button and select Backfill. Choose the date range you want to backfill for, and which runs you want to reprocess. You also have the option to select the number of max active runs for the backfill, whether you want to run backwards or forwards, specify run parameters and select one of three reprocessing behaviors:
- Missing Runs: Creates and runs only the Dag runs that don’t already exist for the selected period.
- Missing and Errored Runs: Creates any missing runs and also re-runs any existing Dag runs that previously failed.
- All Runs: Clears and re-runs all existing Dag runs within the date range, in addition to creating any that are missing.